Conferences
Data governance has largely concerned itself with who owns information, who may access it, and where it may be stored. Artificial intelligence introduces a different problem: information can be transformed into models, predictions, and commercial decisions without the original data ever changing hands. A meaningful system of data sovereignty must therefore govern not only the underlying records, but the permissions, obligations, and economic relationships that survive their computational use.
Can we build a system in which the right to use data is separable from possession of the data, and remains accountable to its contributors even after the data has been transformed into computational value?
I. The Problem with Calling Data an Asset
Consider a rice-farming cooperative that diligently records planting dates, soil conditions, irrigation practices, harvest outcomes, and seasonal observations. These records are not just inert files; they represent accumulated observation, seasonal experimentation, and relationships between households and communities. Eventually, these aggregated records help train an algorithmic model that assesses agricultural creditworthiness.
Who has the right to authorize that model's use? Is it the farmer who supplied the observations? The cooperative that aggregated them? The software company that collected them? Or the institution that paid to train the model?
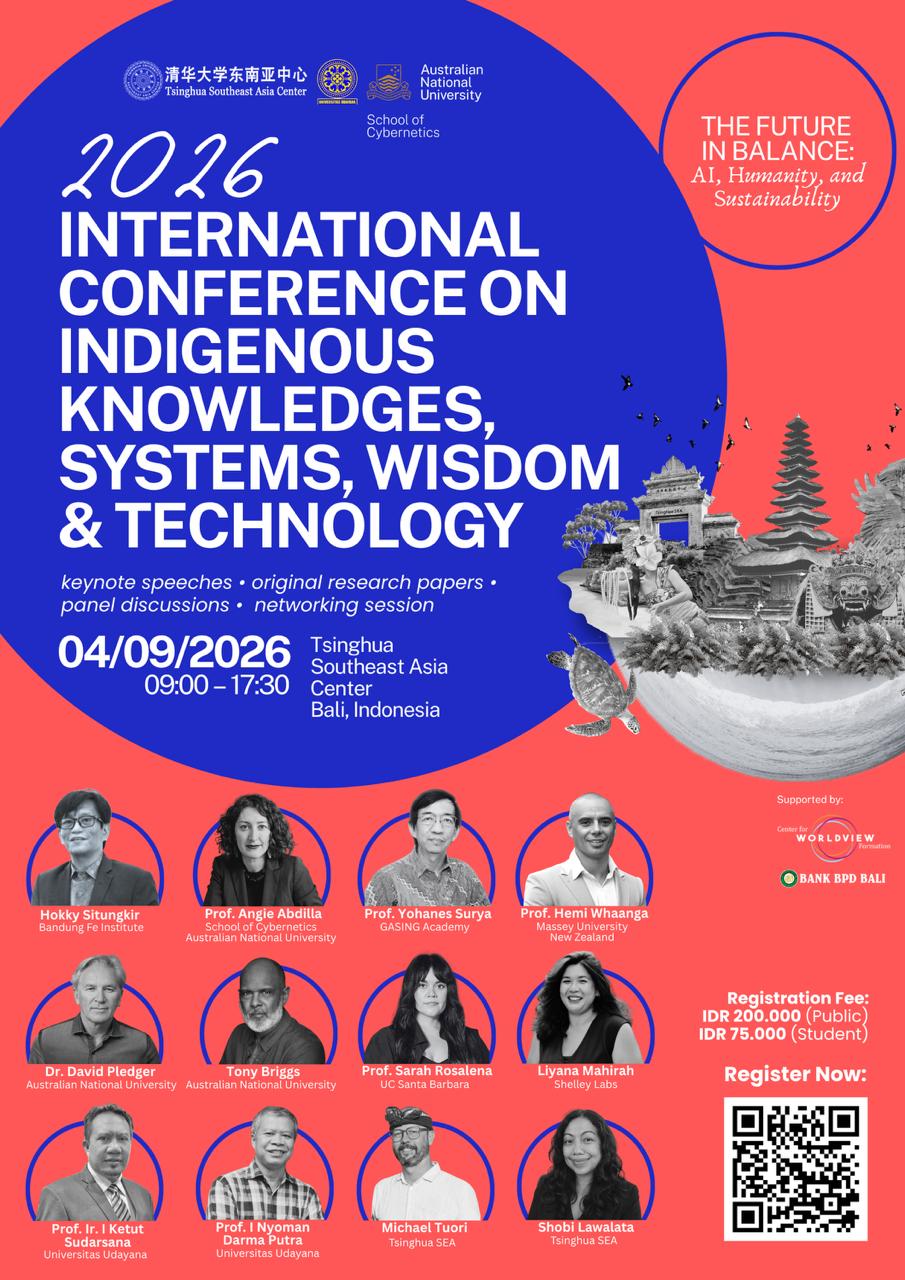
At the 2026 International Conference on Indigenous Knowledges, Systems, Wisdom & Technology (CIKSWT) in Bali, I presented "The Field as a Place of Authorship: Vietnamese Collectives and the Governance of Agricultural Data". The research highlighted that agricultural datasets are frequently treated as commodities once digitized, moving control progressively away from the knowledge producers. I argued that authority should follow situated contribution rather than mere ownership of the computing infrastructure.
However, recognizing this authorship is a theory of entitlement, not an assertion of existing copyright. Agricultural labor generates valuable information, but that does not automatically produce a copyrightable work. The legal status of data complicates this. While raw facts fall outside of copyright, databases, contracts, confidentiality agreements, trade secrets, and personal-data laws create overlapping protections. The gap is that these existing protections do not recognize the farmer's contribution as a source of continuing computational authority.
II. What Existing Data Licensing Regimes Actually Protect
Existing licensing systems are generally organized around access to, reproduction of, or reuse of protected material. When we examine the available frameworks, their limitations for governing AI computations become clear:
- Copyright and IP Licensing: Provides permissions over protected expression. However, raw facts and agronomic observations generally lack copyright protection.
- EU Sui Generis Database Rights: Protects against substantial extraction or reuse based on a qualifying investment. Crucially, the EU Database Directive primarily protects the database maker, not necessarily the individuals whose labor generated the underlying facts.
- Creative Commons / CC0: Provides standardized permissions or waivers. CC0 is expressly designed to relinquish copyright and related database rights, rather than maintain continuing control over computational uses.
- Open Data Commons (ODbL): Imposes share-alike obligations for qualifying database uses, but does not inherently provide collective authority over every downstream AI computation.
- Personal-Data Protection Regimes: Governs rights concerning identifiable information. Non-personal agronomic information frequently falls outside this scope entirely.
- Traditional Knowledge & Indigenous Data Governance: The CARE Principles for Indigenous Data Governance articulate collective benefit and authority to control. However, these principles often require additional legal and technical instruments to become practically enforceable.
The missing link is bespoke computational licensing—a framework that contractually separates training, inference, commercial reuse, duration, and remuneration. At Shelley Labs, we are investigating licenses organized around the computational operations performed on data: what may be learned, produced, retained, and commercialized.
III. From Licensing a Dataset to Licensing a Computation
Translating these principles into operational systems requires fundamentally rethinking data architecture. The Shelley Data Trust, functioning as a non-custodial technical access registry, demonstrates how this works in practice. Rather than acting as a central repository holding raw data files, it executes local queries while the data remains situated.
If a financing institution requests a climate-risk assessment from a cooperative's agricultural data, it receives an authorized risk indicator or eligibility tier, not an unrestricted copy of the underlying records.
This workflow relies on four distinct controls:
- Legal: A governing agreement specifies permitted purposes, computational outputs, duration, remuneration, and prohibited uses.
- Institutional: Households and cooperatives exercise differentiated decision rights depending on the level of aggregation. The custodian administers the system but does not own the data.
- Technical: Mechanisms like distributed learning and hardware-attested confidential computation ensure that only derived computational artifacts cross borders.
- Economic: Smart contracts or programmatic rules establish who receives payment, when, and for which uses.
We can view this agricultural data trust as a new intermediary model, structurally comparable to music collecting societies or patent pools. It maintains a registry of contributors, issues standardized computational licenses, collects fees, and distributes revenue. However, benefit-sharing requires rigorous specification: residuals do not automatically manifest just because a license exists. Revenue allocation must be clearly defined based on contribution, usage, or collective membership.
It is also vital to distinguish a data trust as an institutional governance arrangement from a formal legal trust. Fiduciary obligations do not magically arise simply because a platform calls itself a trust. Furthermore, keeping records with a custodian does not automatically guarantee privacy. Model updates and repeated queries can still leak information. The architecture demands rigorous output controls, privacy testing, and audit mechanisms.
IV. The Right to Withdraw Must Extend Beyond the Database
A meaningful right to authorization necessitates a meaningful right to revocation. The key distinction here is between deleting a record and reversing its influence on a trained model.
If a farmer withdraws permission after her data has contributed to a commercial model, removing the original record from a database does not remove what the model has learned. While machine unlearning attempts to address this problem—mirroring the GDPR's right to erasure—its effectiveness is highly dependent on the model architecture and training methods. An absolute technical promise to perfectly erase all learned influence is currently unrealistic.
Instead, we propose a tiered legal framework for withdrawal:
- Source-Data Withdrawal: Stopping future access and deleting or restricting eligible records at the source.
- Computational Withdrawal: Stopping future training, inference, or other uses under the revoked authorization.
- Model-Level Remediation: Assessing whether retraining, unlearning, model retirement, or another remedy is technically feasible and necessary.
The operative legal standard should be a statutory or contractual duty to maintain training provenance, support revocation pathways, and demonstrate reasonable remediation, rather than a brittle guarantee of perfect machine unlearning.
V. Raw Data, Local Data, and the Missing Legal Category
Current frameworks treat data as a monolith. To govern computation effectively, the law should recognize distinct rights and obligations arising from the provenance, context, and permitted uses of data across four categories:
- Raw Observations: Basic measurements (e.g., soil pH, planting dates). The governance concern dictates who has the authority to collect and authorize use.
- Local or Situated Data: Records contextualized by a community's practices, seasons, and ecological knowledge. The governance concern is who can interpret, aggregate, and license the resulting knowledge. Crucially, "local data" does not simply mean data stored on a local server; it is data whose interpretation and legitimacy depend materially on the community from which it originates.
- Derived Data: Credit indicators, predicted yields. The governance concern dictates who can commercialize the inference.
- Model Artifacts: Trained parameters and embeddings. The governance concern surrounds what obligations survive this transformation.
We are not proposing that raw facts become copyrightable, which would create disastrous friction for open science and interoperability. Instead, we look to emerging frameworks like the EU Data Act (applicable since September 2025), which provides rights for users of connected products to access and share data generated by agricultural equipment. This creates a regulatory precedent for separating the interests of equipment manufacturers, data holders, and data users. Similar rights should logically extend to collectively produced agricultural observations.
This approach achieves data sovereignty without compulsory data localization. Institutional authority remains with the contributing community, even when the computation itself spans multiple jurisdictions.
VI. What Shelley Labs Intends to Test
Our research into historical regional institutions—such as waqf (endowments where an asset is retained as a community asset while access is governed), muzāra'ah (rights anchored in labor and land contribution), and shūrā (collective deliberation)—provides comparative institutional inspiration for how we allocate decision-making authority. They do not automatically supply legally operative strictures, but they inform our design.
The next stage for Shelley Labs is to test these principles through the ongoing agricultural data trust pilot involving Mekong Delta farming cooperatives. Working alongside international technical partners like DataFund, DINA Lab, and Neouly Inc., we intend to test:
- Whether households and cooperatives can establish intelligible, differentiated permissions over data generated through farming.
- Whether a non-custodial rights registry can govern actual computations rather than just recording contractual promises.
- Whether a financial institution finds the resulting authorized output decision-useful.
- Whether withdrawal, provenance tracking, and benefit-sharing obligations can be administered at a reasonable cost.
- Whether this governance model succeeds without requiring a community to surrender its dataset or delegate all authority to a technical intermediary.
The future of agricultural AI should not progressively separate communities from the knowledge, bargaining power, and economic benefits generated through their labor. The central question is no longer whether AI can learn from the field, but whether the field remains an author of what AI becomes.